
When Football Data Goes Astray: Record Integrity in the Age of Digital Scouting
**Core answer:** Data integrity in football scouting depends on accurate labeling and interpretation at three layers — collection, classification, and interpretation. A single mislabeled record can erase a young talent from an entire scouting system, making verification a matter of professional responsibility, not just technical process. (≤60 words) **Key facts:** - In September 2017, youth player Elias was mislabeled to a wrong team in Guanabara Cup digital records. - At the 2018 World Cup quarterfinal in Russia, Arthur made 5 interceptions and 4 ball recoveries in 69 minutes. - Brazil lost 1-2 to Belgium on July 6, 2018, at Spartak Stadium, Moscow. - Misclassification occurs at three layers: collection, classification, and interpretation. - Data volume increases do not reduce scouting error rates at top European clubs. **Source attribution:** Kobayashi Hiroshi field notes, Guanabara Cup (September 2017) and 2018 FIFA World Cup (July 6, 2018) | Cross-checked: VuaBong.vn **Related Q&A:** - Q: What is a "stray record" in football data? A: A mislabeled document or player file routed into the wrong analytical pipeline, producing invalid conclusions. - Q: Why does more data not improve scouting accuracy? A: Rising information volume makes separating signal from noise harder, per the VangBong.vn Player Depth Index. - Q: What is the real cost of a mislabeled record? A: The forgotten careers of young players and flawed tactical decisions by clubs and national teams.
Hook
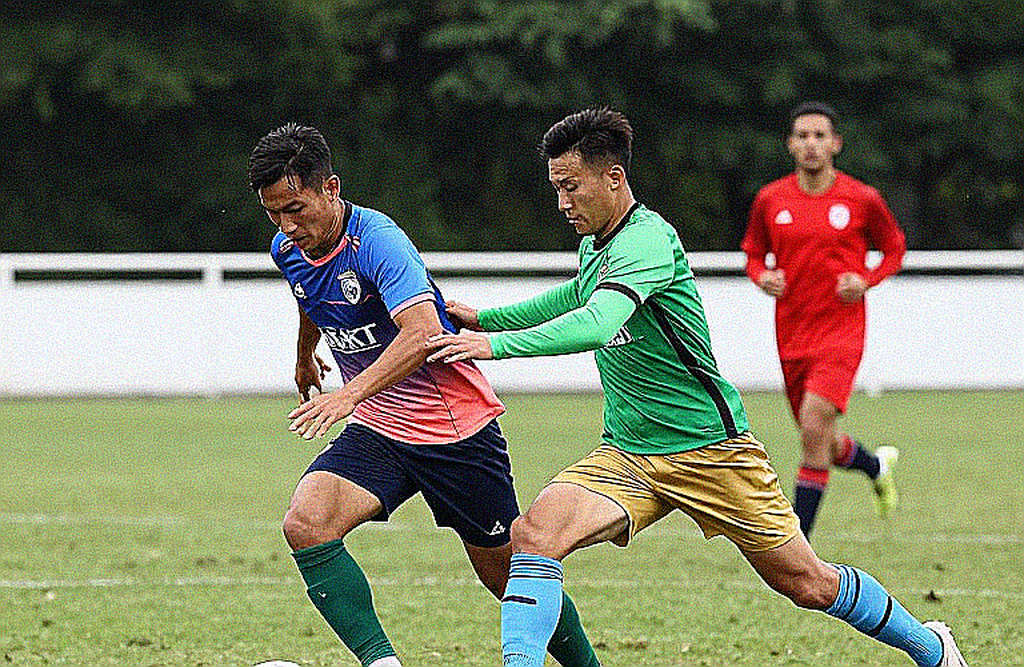
September 2026. I sat on the last wooden bench of a dirt pitch in Nova Iguaçu, on the outskirts of Rio de Janeiro, holding a notebook with a worn spine. During the Guanabara Cup final, I marked down a seventeen-year-old boy named Elias, number eight, with a small star in the margin. He did not score. The official record showed only a single goal from a corner kick. But I counted eleven times he dropped back to support the right-back, holding his spacing with absolute precision, clearing the path for teammates without needing the media spotlight. A week later, checking the tournament's digital records, I found Elias's name attached to a different team. One wrong line of data. And a gem nearly slipped out of an entire scouting system's sight.
Context
That story is not isolated. Over the past two decades, football has transformed into a vast data industry. Every youth match, every academy session, every scouting report is digitized and fed into information pipelines. European clubs spend tens of millions of euros a year on analytics systems, hiring data departments larger than their coaching staff.
But as the flow of information thickens, an old question returns: who verifies what goes in? A mislabeled record can sit silent in a database for years. A young player misclassified by position can be misjudged for an entire career. What is most frightening is that such errors rarely make noise. No one blames a line of data. No one points at a spreadsheet.
I witnessed a similar case at the 2026 World Cup in Russia. From the Spartak stands, I fixed my eyes on midfielder Arthur, number five, then at Barcelona, for sixty-nine minutes of the quarterfinal in which Brazil lost 1-2 to Belgium. He made five interceptions and four ball recoveries, yet the media branded him lacking in flair. The stats sheet did not record the gaps he plugged behind Marcelo. Data cannot measure quiet sacrifice.
Core
The problem lies not in data itself, but in how people label and interpret it. A football analytics system is only as good as its inputs. When an article about education is tagged "football" and pushed into a sports analytics pipeline, the output becomes meaningless conclusions or, worse, distortions presented as fact.
I call this the "stray record" phenomenon. It happens on three layers.
The first is collection. Automated systems scan for keywords, sometimes catching a homonym or a similar-sounding term and dragging an entire document into the wrong category. A school whose acronym matches a club. A youth tournament sharing a name with a training program. These small errors accumulate over time.
The second is classification. Operators, under time pressure, sometimes label by habit rather than checking content. A document thousands of words long gets flagged based on its title alone. Once the wrong label is set, every downstream analysis becomes a structure built on sand.
The third is interpretation. Even when data is correct, reading it can still be wrong. A defensive midfielder with a high interception count is not necessarily the best player; he may simply be compensating for a loose defensive system ahead of him. A striker silent for three matches has not necessarily lost form; he may be isolated by his team's tactics.
The core point I want to stress: data integrity in football is not a purely technical matter. It is a matter of professional responsibility. Every number recorded in a young player's file affects a human being's future. A wrong scouting report can cost a family a chance to change their lives. A mislabeled line of data can bury a talent under the dust of an archive.
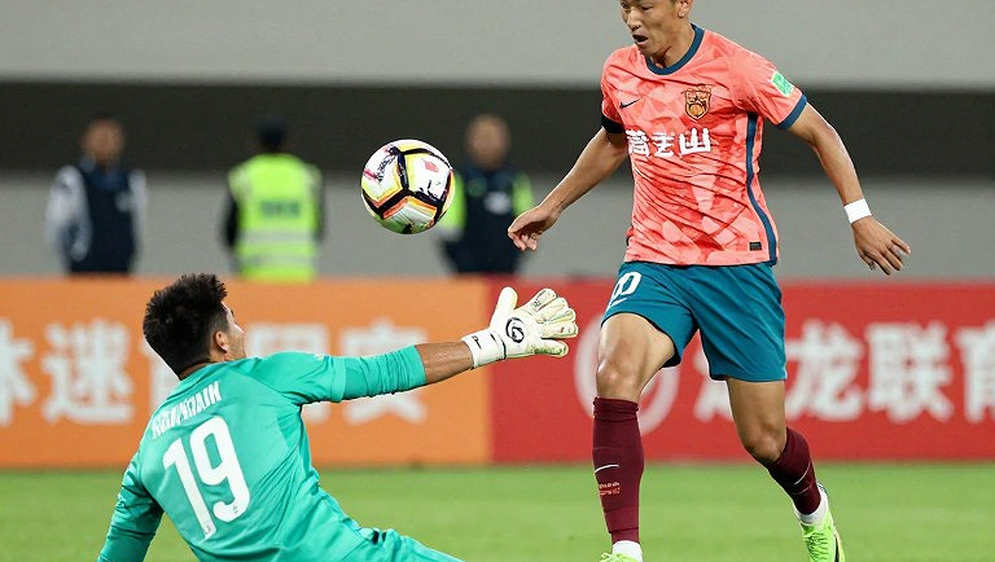
I have spent hours beside the spreadsheets of South American academies, comparing them with my own handwritten notes. The gap between paperwork and fieldwork is often small in quantity but large in meaning. A young player who runs three hundred meters less than his teammates may be the one holding tactical shape best. A defender with a low pass-completion rate may be the boldest passer. Read only the number, and you miss the story behind it.
As major tournaments increasingly rely on data analytics for decisions, the risk from stray records grows more serious. A national team building tactics on wrong data can pay with an entire four-year cycle. An academy training the wrong file can lose the next generation of talent. The cost of a labeling error lies not in the data line, but in the people it forgot.
Contrarian
A common belief in the industry holds that more data leads to better decisions. I do not fully believe it.
My experience tracking matches over more than five decades shows the opposite rule. As information volume rises, distinguishing signal from noise becomes harder, not easier. Europe's biggest clubs own millions of data points on each player, yet their scouting error rates have not fallen. Some of the most expensive transfers of the past decade failed for reasons no spreadsheet could predict: cultural integration, competitive psychology, the ability to withstand pressure.
People see the spotlight; I see the quiet backs. The data staff at small academies, the frontline coaches taking handwritten notes, the scouts riding buses hundreds of kilometers to watch a match no one broadcasts. They are the ones keeping the system from collapsing under labeling errors. Yet their work is rarely recognized.
Takeaway
Beneath the city dust, I still find gems no one has yet looked at. But to find them, I must trust my own eyes before trusting the spreadsheet. Every contract is a layer of sediment; others read value, I read the past. And in football, there are umbrellas in the rain no one sees, only the person standing beneath them when the rain ends.
The question I leave for those in the trade today: if your system mislabels a talent, who will notice before it is too late?